Website development requires the use of numerous technologies and solutions. The rapid development of the industry and growing user expectations necessitate the discovery of new ways to present content. Unfortunately, the appearance of websites and the way their content is rendered don't always meet Google's expectations, as Google has long struggled to render JavaScript-based pages. To this day, SEO for JavaScript-based websites requires a specialized approach.
JavaScript – Theory
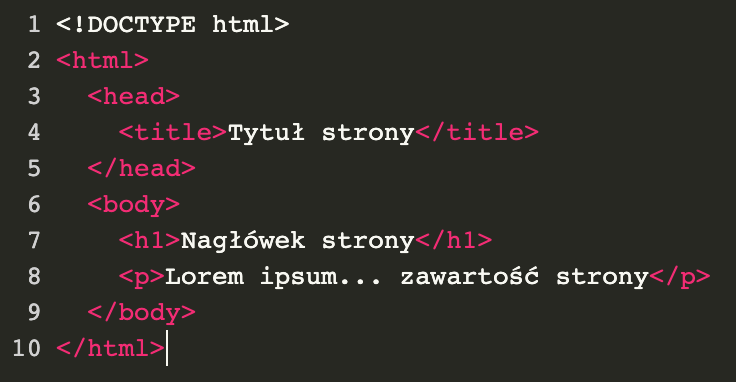
A website is code that is read by browsers and rendered in the desired manner. Subsequent website elements are added using HTML tags:

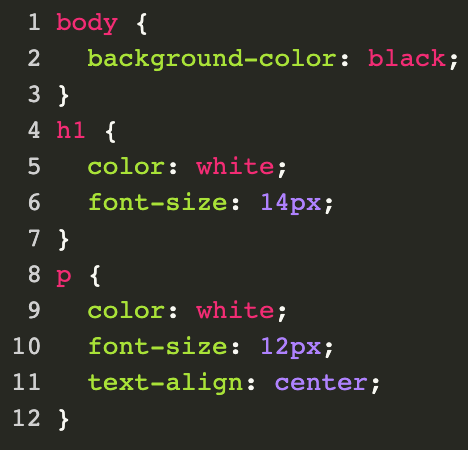
The appearance of the page requires the addition of an additional file written in CSS. Styles are most often located in the style.css file.

Websites built using HTML and CSS are relatively simple. Creating complex services requires the use of more advanced technical solutions, enabling dynamic content delivery, server-level HTML rendering, and processing user information and storing it in a database. The use of additional technologies also allows for more attractive ways to present information on the website.
(The rest of the article can be found below the form)
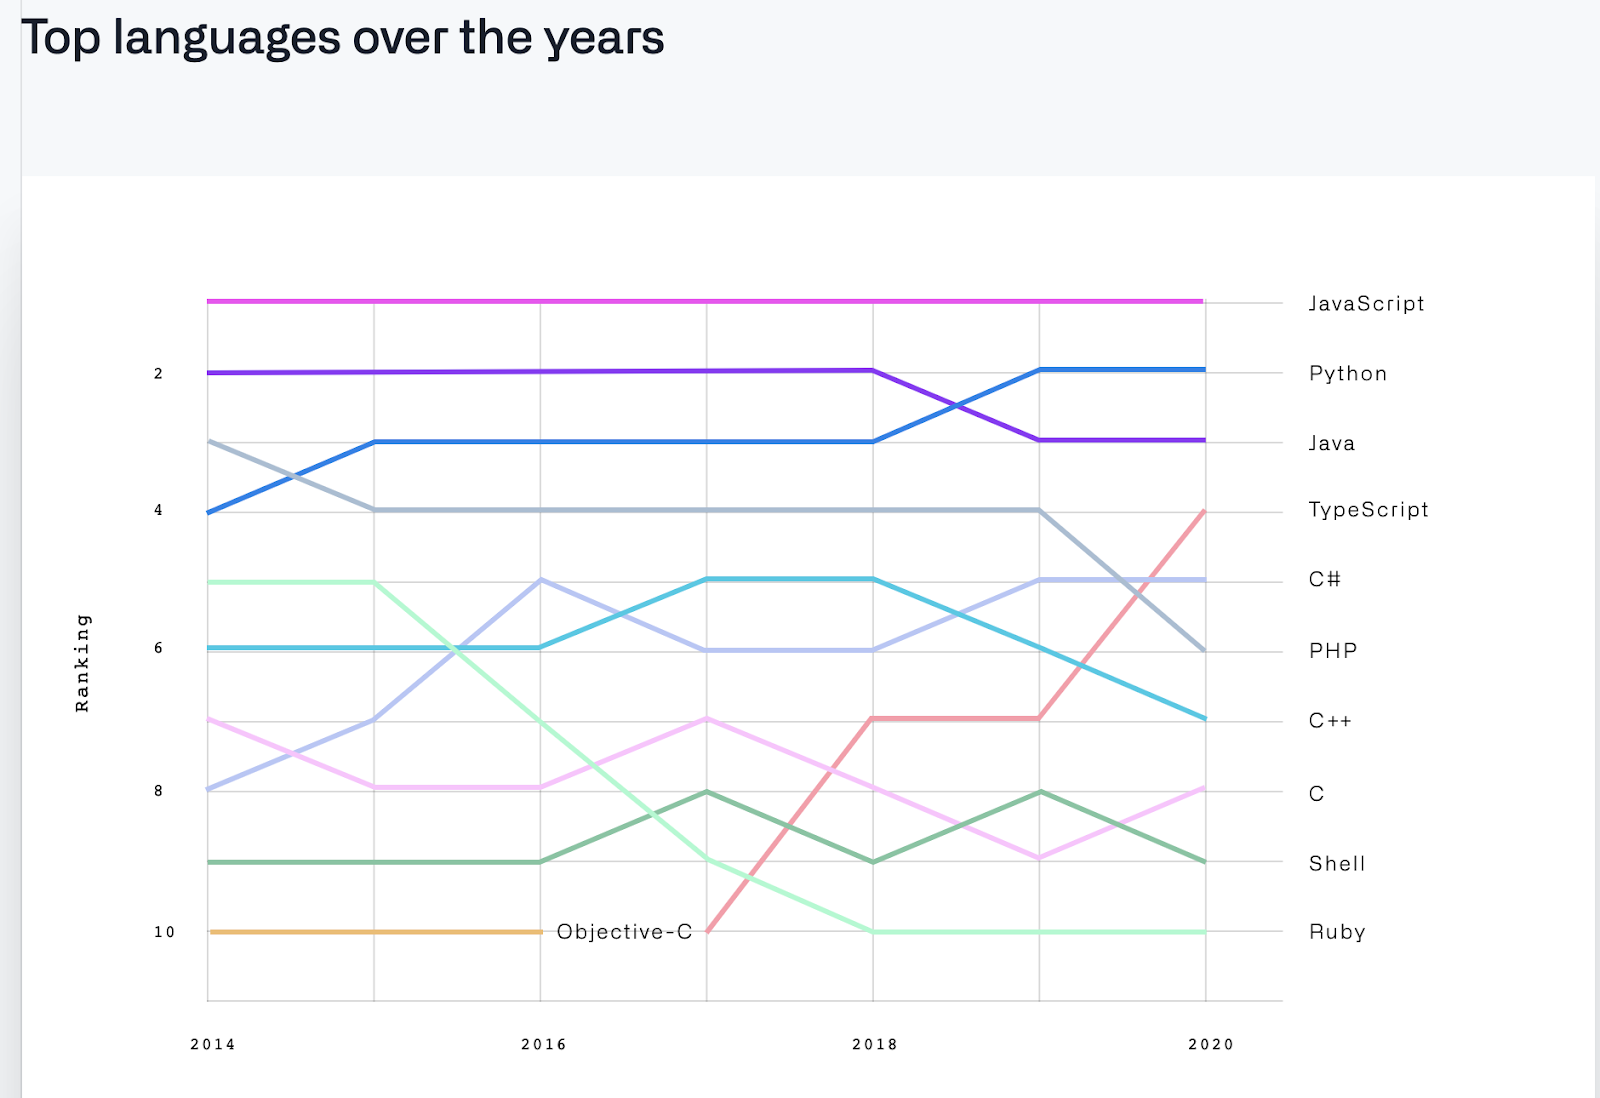
Building dynamic applications is possible thanks to a wide range of programming languages that extend the functionality of websites. In recent years, JavaScript has been one of the most popular programming languages. This is confirmed, among others, by the report "The 2020 State of the Octoverse," which summarizes developer activities within the GitHub platform.

(source: https://octoverse.github.com/ )
JavaScript was created in late 1995. Initially used primarily to validate user-entered information (e.g., ensuring the email address is correct in a form), today it enables the creation of dynamic websites. Thanks to scripts, a website "lives" and responds to user actions – the image gallery becomes interactive, pop-ups can be closed, and Google Analytics collects information about website traffic. JS is also responsible for other elements without which websites seem to fall short of modern standards:
- infinite scroll (i.e. loading subsequent elements, e.g. products, without reloading the page),
- comments and ratings,
- internal linking,
- lists of “the best” products or articles.
Choosing JavaScript as the technology on which the website will be based allows you to place elements downloaded from external sources, such as the Google Maps API or APIs from social networking sites.
JavaScript code is stored in a file saved as .js (usually script.js) – a link to it is inserted in the head section of the page or immediately before the final body tag (which is recommended). However, some code fragments are also placed directly between HTML tags (e.g., the script responsible for Google Analytics ), which allows the code to execute (i.e., a specific action to occur on the page) before the entire HTML and CSS structure is loaded. Unfortunately, such manipulations usually have a negative impact on the website's rendering speed – so it's best to use this option sparingly.
Within websites built according to this standard, the HTML structure is first loaded, then supplemented with CSS code. Finally, the JS code is executed, following the order of the elements in the file – from top to bottom.
You can learn about the technologies a website uses using tools such as https://www.netcraft.com/. Browser-based tools allow you to view any JS script errors, such as Chrome's DevTools (right-click -> Inspect), "Console" tab.
Client-side rendering or server-side rendering?
JavaScript is a unique language – it can be executed server-side or browser-side. Both options allow you to build a modern web application that appeals to both users and web crawlers.
Server-side rendering (SSR) is the most popular method of displaying web pages. The browser sends information to the server, which responds with rendered HTML, which is then displayed on the screen. Response speed depends on factors such as:
- internet connection,
- server location (distance from the computer from which the query was sent),
- traffic on a given website (how many queries are sent at the same time),
- from website optimization, e.g. caching and the ability to store some files in the browser cache).
Each subsequent click requires the page to be reloaded – the server sends a response containing HTML, containing the same elements as the previous subpage.
Client-side rendering allows for rendering responses on the client side—usually the web browser. In this case, in response to a browser request, the server sends a JavaScript file responsible for creating the HTML structure and adding content to it. When navigating to a new subpage, the website doesn't need to be reloaded—JS retrieves the necessary content from the server and adds it to the previously rendered HTML framework. Server response is faster, and the internet connection is less congested.
Client-side rendering is typically faster, but because all the JS code must execute, the initial site load can be longer than with SSR. Client-side rendering—rendering a view only for a given browser—can cause problems with effective website SEO.
Google vs. JS – a bumpy road to success
The possibilities offered by JavaScript code have significantly contributed to its popularity. JavaScript allows, among other things, the creation of dynamic pages based on a template written in HTML and CSS, supplemented with data retrieved from databases, for example. Furthermore, the potential inherent in this language allows for the manipulation of templates, the creation of additional elements, and the rendering of pages "on the fly" – while the program is executing. This principle was used in the early years of its existence by, among others, the Wix website builder – rendering websites based on JavaScript code.
Unfortunately, as I mentioned above, this solution isn't conducive to achieving high rankings in Google. For many years, the Mountain View-based company's web crawlers were unable to properly analyze JavaScript pages, which in turn resulted in an inability to compete in the SERPs. In recent years, Google has claimed to be improving its capabilities in this area, but the efficiency of reading code files isn't always satisfactory.
Positioning JavaScript pages first requires understanding how Googlebot processes JavaScript code. For static pages, the robot's logic is quite simple:

Google checks whether it can access a given address (robots' access may be blocked in the robots.txt file or tag in ), then downloads the page data – the HTML structure – and simultaneously checks the contents of all links in the code. Next, the CSS files are read and the page is submitted for indexing.
For JavaScript pages, the process is different:

As you can see in the attached diagram, the path Googlebot must take is much more complex. After downloading the HTML file, it downloads the CSS and JS code necessary to render the page. It then supplements it with resources downloaded from external sources (if any) and renders the page. The page's appearance and essential structural elements are contained in the JS code, which allows for the manipulation of individual fragments and customization to the user's needs.
Rendering the code before indexing can take time, and Google doesn't guarantee that it will retrieve all the information we intended to include on the page. This is due, among other things, to the number of URLs the robot scans daily—the so-called "crawl budget." Taking Googlebot's needs into account allows it to crawl effectively, which translates into a site's visibility in search results.
Mapping the Googlebot path provides a clear understanding of the complexity of SEO for JavaScript-based websites . Unfortunately, it doesn't provide any insight into the risks and issues that may arise during subsequent steps. Let's take a closer look...
You might like it
JS Pages – What Does Google See?
Websites based largely on JavaScript have always posed a significant challenge for Google's crawlers. Their indexing levels are increasing, but they're still not as robust as we'd like.
Google renders pages differently than the average browser, and the way a user interacts with a page is also different. The algorithm focuses primarily on elements necessary to render the site. It may ignore those it deems less important and, as a result, fail to include them in its indexing. This is especially problematic when these fragments contain content intended to ultimately lead to high search results . Data dependent on cookies is particularly vulnerable to being invisible – if the content is served based on cookies, Google will likely not access it. Additional issues include the speed at which the code executes – poor optimization can prolong the entire process and result in the crawler abandoning it.
The second problem is the lack of Googlebot activity during a visit to the site – Google doesn't scroll the page, doesn't click where the user clicks, and blocks automatic video playback. Unlike other site visitors, they may not be able to access all the prepared content and may not have a complete understanding of the site.
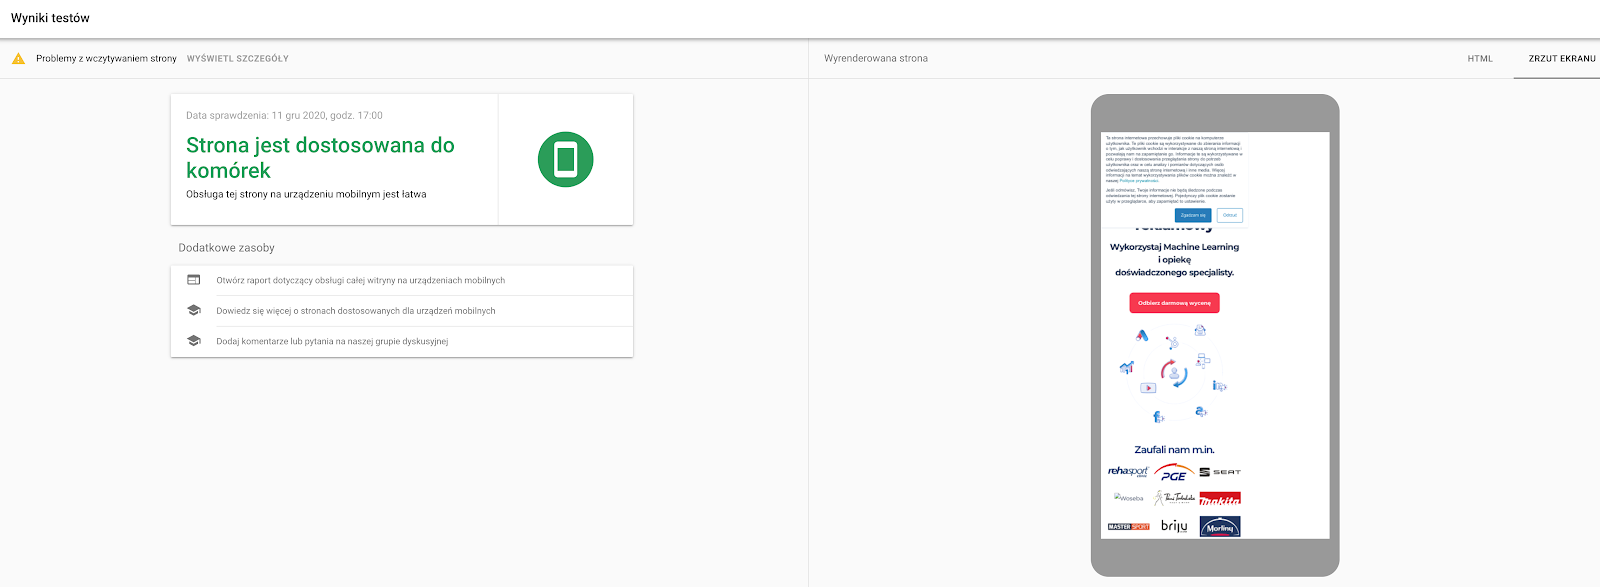
You can learn how Google renders your website using the Mobile-Friendly Test (https://search.google.com/test/mobile-friendly?hl=pl). After entering the address, Mobile Test will download the specified subpage and return information about the rendering process, including any error messages. A preview of the rendered page will also appear on the right.

Information about problematic elements is available under the "Page loading problems" button.
You can also check your page in Google Search Console – "URL Check." Both forms of checking how your website is rendered allow you to obtain the data necessary to make any necessary changes and improve the indexing of your JS-based website.
Single Page Apps – React, Vue.js and other frameworks
The increased emphasis on data delivery speed and the popularity of technologies used in mobile applications have led to the rise in popularity of single-page apps. This type of website has a single HTML file used to render subsequent subpages. Content is retrieved dynamically from the server via JS requests.
SPAs are fast and well-received by users. During the visit, the browser downloads all static elements, while the remaining content is loaded during the visit. Transitions between subsequent sections of the page are dynamic, eliminating page reloads. From the user's perspective, they appear the same as more traditional pages. For example, links in the menu have the familiar "About Us" format, but after clicking them, the browser doesn't retrieve data from the next HTML file. In fact, it remains in the basic index.html file, and the "about-us" content is retrieved from the database and rendered using JavaScript.
Single-Page Apps (SPAs) are built using the AJAX model, which allows for asynchronous communication with the server, eliminating the need to refresh the document for each user interaction with the website. Pages are built using frameworks, which Wikipedia calls "application building frameworks." A framework is responsible for the application's structure, mechanism of operation, components, and necessary libraries. The most popular frameworks include React, which is used to build application interfaces. Vue.js and Ember.js are also frequently used. The framework developed and promoted by Google is called "Angular." The most popular frameworks allow for server-side rendering of websites (which is recommended for easy crawling by Googlebot) and accommodate the requirements of mobile browsers.
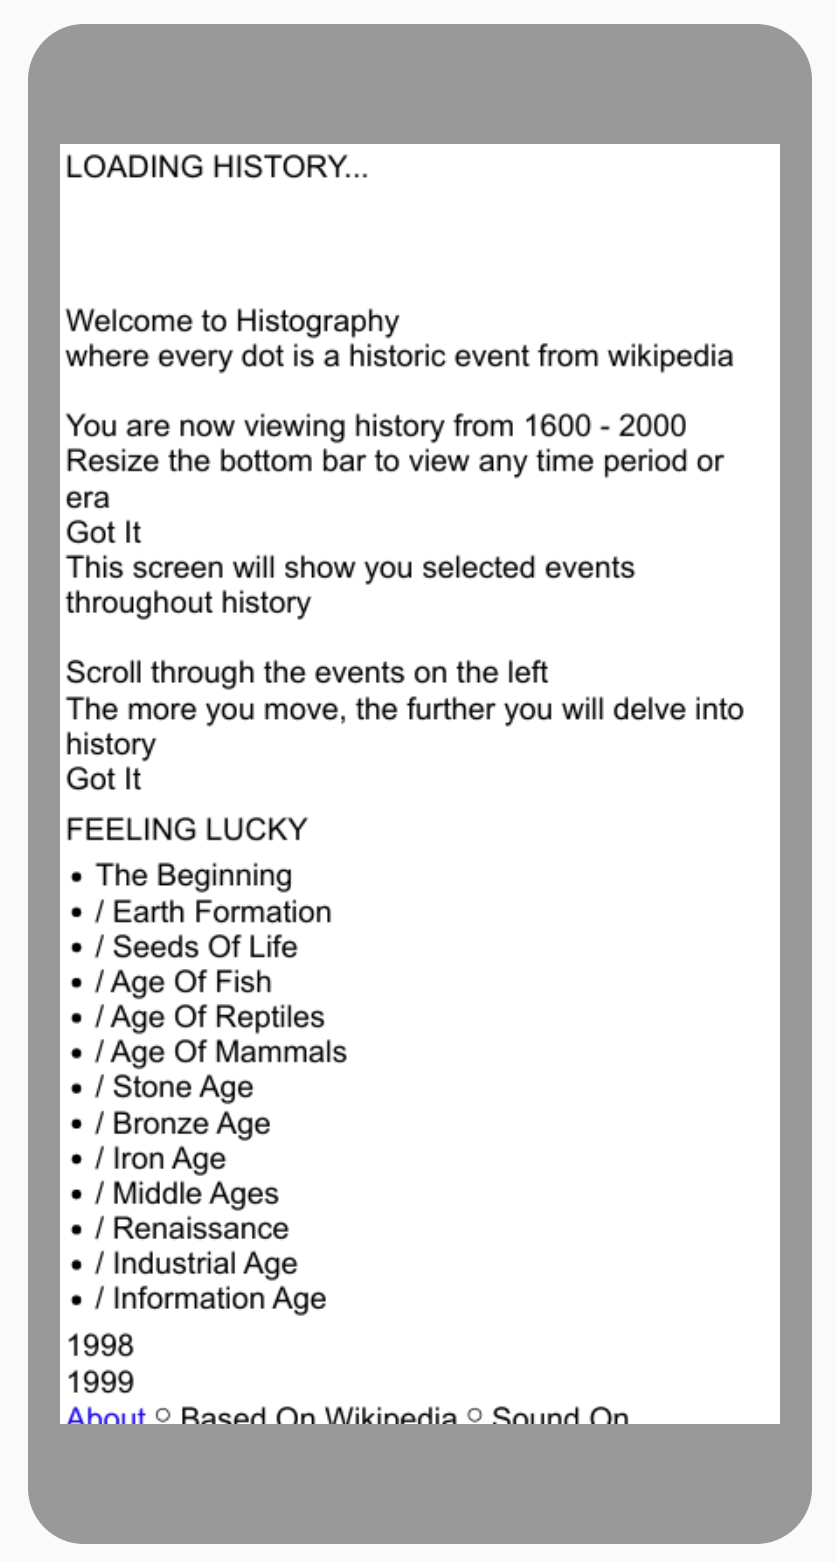
As I mentioned earlier, Google doesn't always handle these types of sites, which makes SEO for some JavaScript-based single-page apps impossible without proper optimization. A good example is http://www.histography.io/ . The site provides a wealth of historical information (taken from Wikipedia), but Google doesn't see its potential:

Google's index includes the home page and two random PDFs. Web crawlers also can't access the home page content and only see this:

While a lack of presence in Google isn't significant for this type of website, for a retail store it can significantly impact customer engagement. Sites created using popular frameworks like React, Vue.js, or Angular allow for the introduction of elements essential for Google's index and serve content in a way that allows for competitive rankings.
Positioning and optimization of JS pages
JavaScript-enabled solutions have a positive impact on website speed and user experience. However, viewing your page by potential customers is only half the battle – most of them only land on your URL once they find it in Google search results.
Optimizing websites with a lot of JavaScript code requires making changes that seem obvious for static websites.
Access for web robots
As mentioned earlier, Googlebot will first check whether the URL it encounters is accessible. This applies to all resources within it, including JS and CSS files. Rendering JS pages by Google requires full code access, so you should avoid blocking these resources in your robots.txt file.
URLs
One of the problems you may encounter when optimizing a website that relies heavily on JS is the lack of "traditional" links to subsequent subpages. Googlebot focuses only on links placed in the href attribute of the tag .
Another problem with URLs typical of JS-heavy sites is the use of addresses with "#." The hash mark allows you to skip scrolling and go directly to the selected fragment.
One solution to these problems is to use the HTML5 History API. It allows for manipulation of browser history—for example, changing the address in the browser's address bar and changing content—without having to reload the page. The API is built into most frameworks (including React Router), making it much easier to build pages that rank well in Google . Note: these solutions won't work with older browser versions.
Among other URL issues, it's worth noting the significant potential for duplicate pages, with addresses differing in case or ending with a slash. This problem is resolved by placing them in the canonical link. The address contained in them will be unambiguous information for Google.
sitemap.xml
A factor that greatly facilitates website indexing is the sitemap, a file containing links to all addresses within a domain. A sitemap is a list that should include all the addresses to which we want to invite the bot.
Redirects and the problem of soft 404 errors
One of the key elements of website optimization is identifying broken URLs and redirecting them to new, correct ones. 301, 302, and so on redirects are performed on the server. However, this solution isn't possible with Single Page Apps. As suggested by the Google Help Center and confirmed by tests conducted by Search Engine Land, appropriate use of JS code will work in a similar manner.
A JS redirect will redirect the address to another subpage, but it won't provide the response typical of server-based redirects. However, from a search engine ranking perspective, this isn't a problem. The redirect effectively replaces the old address with a new one, which can climb higher in the rankings.

window.location.replace replaces the current document with the one located at the specified address. The address and content of the original document are not cached. This type of operation is another example of the effective use of the previously mentioned HTML5 History API.
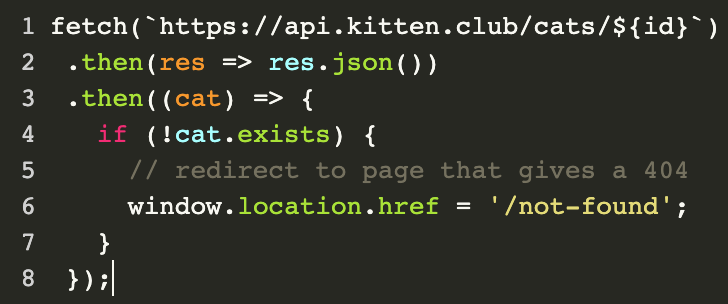
Other server response codes important for web crawlers include 404, "Not Found." For JavaScript pages (although this problem also occurs with poorly configured static pages), the server will interpret the absence of a document at the specified address as a valid 200 response. As a result, the search engine's index may include non-existent addresses containing no content. To mitigate this problem and inform crawlers to consult other subpages, it's worth supplementing the code with a snippet that allows for the desired response from the server. Here's an example from Google Search Central:

Additionally, it is also recommended to block robots from indexing a given address by adding the “noindex” directive to the robots tag.
Loading delay
Page speed is one of the key factors in a website's visibility. Optimal delivery speeds for content and other elements allow for comfortable use of the website without excessively burdening the user's internet connection. One of the most effective solutions is lazy loading – delaying the loading of certain website elements. Note – incorrect implementation can block access to important website resources and, as a result, prevent Googlebot from accessing content crucial for SEO.
During loading, priority should be given to the HTML structure, which allows for the "construction of the page," and its content. Next in line are graphics, which often have the greatest impact on the amount of data retrieved to load the site. Lazy loading allows subsequent elements visible on the screen to be rendered first, allowing for later loading of fragments accessible by scrolling down.
Titles, descriptions…
Without optimizing titles and descriptions, effective SEO is impossible. For single-page apps based on frameworks like React, Ember, or Angular, it's worth considering adding a module or library that allows for the free modification of these tags. For apps built on React, the most frequently chosen libraries are React Router and React Helmet. The React-based Gatsby framework is also becoming increasingly popular.
Testing and troubleshooting JavaScript application positioning issues
For many years, positioning websites based on JavaScript was impossible. Developing methods to deliver content to web crawlers has been coupled with Google's improved ability to render and read JavaScript sites. However, there's still a significant risk of errors when indexing our website's content – the solution provided by Google isn't perfect.
Guaranteeing your site's appearance in the SERPs requires allowing Google robots to access your site and monitoring the content they display. To achieve this, it's important to go beyond testing your site, especially using the Google tools mentioned earlier.
Dynamic rendering – ready for Googlebot
To improve Googlebot's relationship with JavaScript, Google's documentation suggests various tricks to better process JavaScript code. One of these is dynamic rendering.
Dynamic rendering is based on identifying the client (e.g., a browser or web crawler) and providing it with a response tailored to its technical capabilities. In practice, when a query is executed by the user (web browser), the page will be rendered normally – an HTML file will be downloaded, and the desired content will be retrieved from the database using a request sent by a JS script. When Googlebot requests a URL, the server will respond with a page render containing static HTML, enabling faster indexing of its content.
To implement dynamic rendering, you can use an API called Rendertron, which acts as a standalone HTTP server. It renders URL content in a way that's readable by bots that don't properly execute JavaScript. Rendertron allows you to cache the rendered file, significantly speeding up response times to the bot. The cached data will update automatically at predefined intervals.
Pre-rendered documents are also useful from the point of view of other clients – they allow you to prepare content suitable for readers used by blind people.
Website positioning and JavaScript – summary
The growing emphasis on content serving speed will undoubtedly result in further growth in JavaScript's popularity. Google is also taking this into account and is constantly working to improve the indexing of content accessed via JavaScript. Proper optimization and the use of bot-friendly solutions are key to high search results , even for single-page apps and other JavaScript-based websites.
FAQs about SEO and JavaScript
JavaScript itself isn't inherently bad and offers enormous potential for building modern websites. However, the problem arises when it's implemented carelessly. Relying entirely on client-side rendering can pose a significant barrier to search engine crawlers.
Unlike regular HTML pages, Google uses two-wave indexing. In the first wave, the crawler (Googlebot) only downloads the basic, static HTML. Only in the second wave (which can occur after several days or weeks due to resource constraints) does the page enter the render queue (WRS), where JS scripts are executed and the target content is fetched.
The biggest risk for crawlers is the so-called "blank page" in the first phase of indexing – key text, meta tags (Title, Description), and headings may be invisible. Navigation is another huge problem. If internal links are handled solely by JS events (e.g., onclick), Google won't follow them; crawlers require standard href tags.
Server-side rendering (SSR) is currently one of the most recommended practices. It involves processing scripts directly on the server, and then sending a ready-made, fully rendered HTML document to the user's browser (and search engine crawlers). This allows the bots to see all the content immediately.
An alternative is to implement what's known as Dynamic Rendering. This mechanism recognizes who is visiting the page (the so-called User-Agent). Regular users receive a full, dynamic version of the page with JavaScript code, but upon detecting a search engine robot (e.g., Googlebot), the server generates and sends it a ready-made, static, and "light" HTML version, ensuring trouble-free indexing.
Summary
The above article covers the following topics:
- theoretical foundations of JavaScript,
- Google and JavaScript indexing,
- what Google recognizes on JavaScript pages,
- how to position JavaScript-based websites.